On this page
- Why the same GPU has so many prices
- Which card does which job in a voice stack
- L4 prices: the cheapest card for speech to text
- L40S prices: the usual card for text to speech
- H100 prices in the US and India
- B200 prices: the most throughput per card, at the highest hourly price
- Rent, reserve or buy: what each choice costs
- Sources
Why the same GPU has so many prices
Three kinds of seller rent data-centre GPUs, and they price differently. Hyperscalers such as AWS, Google Cloud and Azure charge the most on demand but discount heavily for commitments. GPU-focused clouds, often called neoclouds, such as Lambda, RunPod and CoreWeave, publish on-demand prices close to a hyperscaler's three-year rate, without the commitment. Indian clouds such as E2E Networks and Yotta sell capacity inside India, which matters for data residency.
The term you sign moves the price nearly as much as the seller. On-demand means pay by the hour with no commitment. A reservation, which AWS also sells as a Savings Plan and Google as a committed use discount, trades a one- or three-year promise for a lower rate: 25 to 37% off on demand for one year at AWS, Google and Azure, and 45 to 57% off for three. Spot or interruptible capacity is cheaper still, but the provider can take it back at short notice. Serverless platforms such as Modal bill per second of use.
The tables below were checked on 24 October 2026. Prices for 8-GPU instances are divided by eight to give a per-GPU figure. Rupee prices for US providers are a straight conversion at ₹95.04 per dollar, before taxes, and Indian providers' prices are shown as listed, which for E2E and JarvisLabs means before 18% GST.
Sonex Labs sells the per-use alternative to renting any of these cards, speech and LLM APIs priced per character, second and token, so it has an interest in how this comparison reads. Every price below is a third-party list price with its source.
Which card does which job in a voice stack
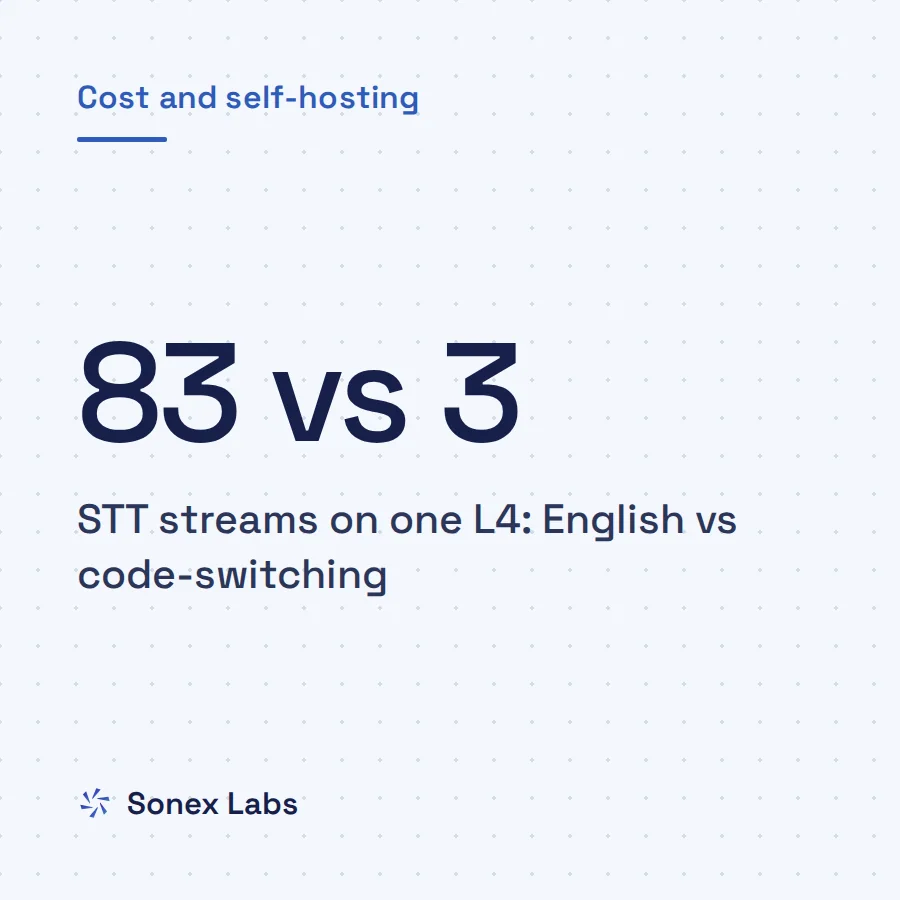
For voice, each card tends to do one job, and the job decides which price matters. The L4 (24 GB, 72 W) carries 48 low-latency speech-to-text streams in NVIDIA's Riva tests (NVIDIA Riva ASR performance). The L40S (48 GB) carries 32 text-to-speech streams for NVIDIA's own multilingual TTS model, with a 133 ms average first audio chunk.
Language models need more. Softcery models 40 to 75 concurrent voice sessions per H100. In NVIDIA's benchmark of an 8-billion-parameter LLM, first-token time on an L40S was 618 to 778 ms at 25 to 100 concurrent requests, against 268 to 615 ms on an H100, so the L40S is a budget LLM card at best. The B200 is the newest and most expensive card; Pipecat ran 44 agent processes on each one for its PhoneLLM model.
An hourly price only becomes a cost per call once you divide by the streams the card carries and by how busy your calls keep it, which for business-hours traffic is often under a quarter of the time. The self-hosting cost model does that division for every component, and how many concurrent calls a 24 GB GPU carries shows how to measure the stream count.
L4 prices: the cheapest card for speech to text
An L4 costs $0.44 to $0.81 an hour on demand, and a three-year AWS reservation brings it to $0.369. Because one card carries dozens of speech-to-text streams, the L4 is usually the cheapest self-hosted component in a voice stack. No sourced price for buying a single L4 server was found, so there is no owned row.
| Provider and term | USD per GPU-hour | ₹ per GPU-hour |
|---|---|---|
| AWS g6.xlarge, on-demand / spotSource: Vantage | $0.805 / $0.640 | ₹77 / ₹61 |
| AWS, 1-year / 3-year reservedSource: Vantage | $0.524 / $0.369 | ₹50 / ₹35 |
| Google g2-standard-4, on-demand / spotSource: gcloud-compute.com | $0.707 / $0.423 | ₹67 / ₹40 |
| Google, 1-year / 3-year commitmentSource: gcloud-compute.com | $0.445 / $0.318 | ₹42 / ₹30 |
| RunPod Secure / CommunitySource: RunPod | $0.59 / $0.44 | ₹56 / ₹42 |
| Modal, billed per secondSource: Modal | $0.80 | ₹76 |
| E2E Networks (India), on-demandSource: E2E Networks | $0.52, or $0.61 with GST | ₹49 before GST |
L40S prices: the usual card for text to speech
An L40S rents for $0.79 to $2.25 an hour, and owning one in a small server works out at about $0.74. Text to speech is the most expensive line in a voice API bill, so this is the card where self-hosting tends to pay off first.
The owned figure assumes a $6,199 card plus $3,800 for the rest of the server, $10,000 in all, drawing 0.6 kW at $300 per kW-month for colocation, with 10% a year for maintenance and no resale. That is $278 + $180 + $83 = $541 a month, or $0.74 per GPU-hour. It beats AWS's three-year price of $0.804 only if the card stays in service and busy for the full three years.
| Provider and term | USD per GPU-hour | ₹ per GPU-hour |
|---|---|---|
| AWS g6e.xlarge, on-demand / spotSource: Vantage | $1.861 / $1.559 | ₹177 / ₹148 |
| AWS, 1-year / 3-year reservedSource: Vantage | $1.172 / $0.804 | ₹111 / ₹76 |
| RunPod Secure / CommunitySource: RunPod | $1.09 / $0.79 | ₹104 / ₹75 |
| Modal, billed per secondSource: Modal | $1.95 | ₹185 |
| CoreWeave, on-demand / spot (8-GPU instance ÷ 8)Source: CoreWeave | $2.25 / $0.99 | ₹214 / ₹94 |
| E2E Networks (India), on-demandSource: E2E Networks | $1.07, or $1.27 with GST | ₹102 before GST |
| Yotta Shakti Cloud (India), 1× VM / 4× bare metalSource: Yotta | $1.44 / $2.07 | ₹137 / ₹197 (GST not stated) |
| Owned 1× L40S server, 3 years, no resaleSource: Our arithmetic | $0.74 | ₹70 |
H100 prices in the US and India
H100 prices spread the widest: $1.29 an hour for Azure spot capacity, $2.69 to $4.29 on demand at Lambda and RunPod, and $11.06 on demand at Google. A committed hyperscaler price can beat a neocloud's on-demand one: AWS's three-year Savings Plan at $2.97 per GPU costs less than RunPod Secure at $3.99, but only if you can forecast three years of load. Even at that rate an LLM GPU has to be busy about 43% of the time to beat a cached mini-class API, as critical utilisation shows.
In India, E2E Networks lists ₹379.05 an hour on demand and says committed contracts start at ₹347.70, both excluding GST (E2E Networks H100). JarvisLabs, which added an Indian region in 2026, lists an H100 SXM at ₹330.48 an hour plus GST, billed per minute (JarvisLabs, updated 20 October 2026). Yotta's dedicated H100 at ₹1,96,113 a month works out at ₹269 an hour over 730 hours, though its page does not say which term that price is for.
| Provider and term | USD per GPU-hour | ₹ per GPU-hour |
|---|---|---|
| AWS p5.48xlarge, on-demand / spot (24-hour range)Source: Holori | $6.88 / $3.16–4.67 | ₹654 / ₹301–444 |
| AWS, 1-year / 3-year EC2 Instance Savings PlanSource: Holori | $4.33 / $2.97 | ₹412 / ₹282 |
| Google a3-highgpu-1g, on-demand / spotSource: gcloud-compute.com | $11.06 / $6.60 | ₹1,051 / ₹627 |
| Google, 1-year / 3-year commitmentSource: gcloud-compute.com | $7.67 / $4.86 | ₹729 / ₹462 |
| Azure NC40ads H100 v5, on-demand / spotSource: Azure Retail Prices API | $6.98 / $1.29 | ₹663 / ₹123 |
| Azure, 1-year / 3-year reservedSource: Azure Retail Prices API | $5.24 / $3.84 | ₹498 / ₹365 |
| Lambda, PCIe 1× / SXM 8×Source: Lambda | $3.29 / $3.99 | ₹313 / ₹379 |
| RunPod SXM, Secure / CommunitySource: RunPod | $3.99 / $2.69 | ₹379 / ₹256 |
| Modal, billed per secondSource: Modal | $3.95 | ₹375 |
| CoreWeave, on-demand / spotSource: CoreWeave | $6.16 / $2.46 | ₹585 / ₹234 |
| Together dedicated / clusters; Fireworks on-demandSource: Together AI, Fireworks | $5.49 / $3.99; $8.00 | ₹522 / ₹379; ₹760 |
| E2E Networks (India), on-demand / committed / spotSource: E2E Networks | $3.99 / $3.66 / $0.74 before GST | ₹379.05 / ₹347.70 / ₹70 |
| JarvisLabs (India region), H100 SXM on-demandSource: JarvisLabs | $3.48 before GST | ₹330.48 |
| Yotta (India), 1× VM / 8× bare metal / dedicated monthlySource: Yotta; monthly ÷ 730 is our arithmetic | $3.75 / $3.69 / $2.83 | ₹356 / ₹351 / ₹269 (GST not stated) |
| Owned 8× H100 server, 3 years, no resale / with resaleSource: Our arithmetic | $2.28 / $1.35 | ₹217 / ₹128 |
B200 prices: the most throughput per card, at the highest hourly price
A B200 rents for $5.98 to $14.24 an hour, 1.4 to 2.1 times an H100 at the same provider. AWS does not publish reserved prices for its B200 instance. New 8×B200 servers cost about $400,000 to $500,000 according to third-party estimates, but no sourced power figure was found, so no owned cost is worked out here.
| Provider and term | USD per GPU-hour | ₹ per GPU-hour |
|---|---|---|
| AWS p6-b200.48xlarge, on-demand / spotSource: Vantage | $14.24 / $10.40 | ₹1,354 / ₹988 |
| Lambda, 8× / 1×Source: Lambda | $6.69 / $6.99 | ₹636 / ₹664 |
| RunPod Secure / Community / ServerlessSource: RunPod | $7.99 / $5.98 / $8.64 | ₹759 / ₹568 / ₹821 |
| Modal, billed per secondSource: Modal | $6.25 | ₹594 |
| CoreWeave, on-demand / spotSource: CoreWeave | $8.60 / $4.26 | ₹817 / ₹405 |
| Together dedicated / clusters; Fireworks on-demandSource: Together AI, Fireworks | $8.99 / $8.19; $13.00 | ₹854 / ₹778; ₹1,236 |
| E2E Networks (India), on-demand / committedSource: E2E Networks | $7.99 / $7.19 before GST | ₹759.05 / ₹683.05 |
| Yotta (India), 8× bare metal (term unclear, indicative)Source: Yotta | $4.98 | ₹473 (GST not stated) |
Rent, reserve or buy: what each choice costs
The cheapest hourly rate is not the cheapest choice unless the load is there to use it. Renting on demand costs the most per hour but nothing when idle; reserving costs less per hour but commits you to paying for hours you may not use; owning costs least per hour and commits you furthest. When to move from one to the next, as your call data firms up, is covered in the break-even-first deployment guide.
What owning a GPU server costs
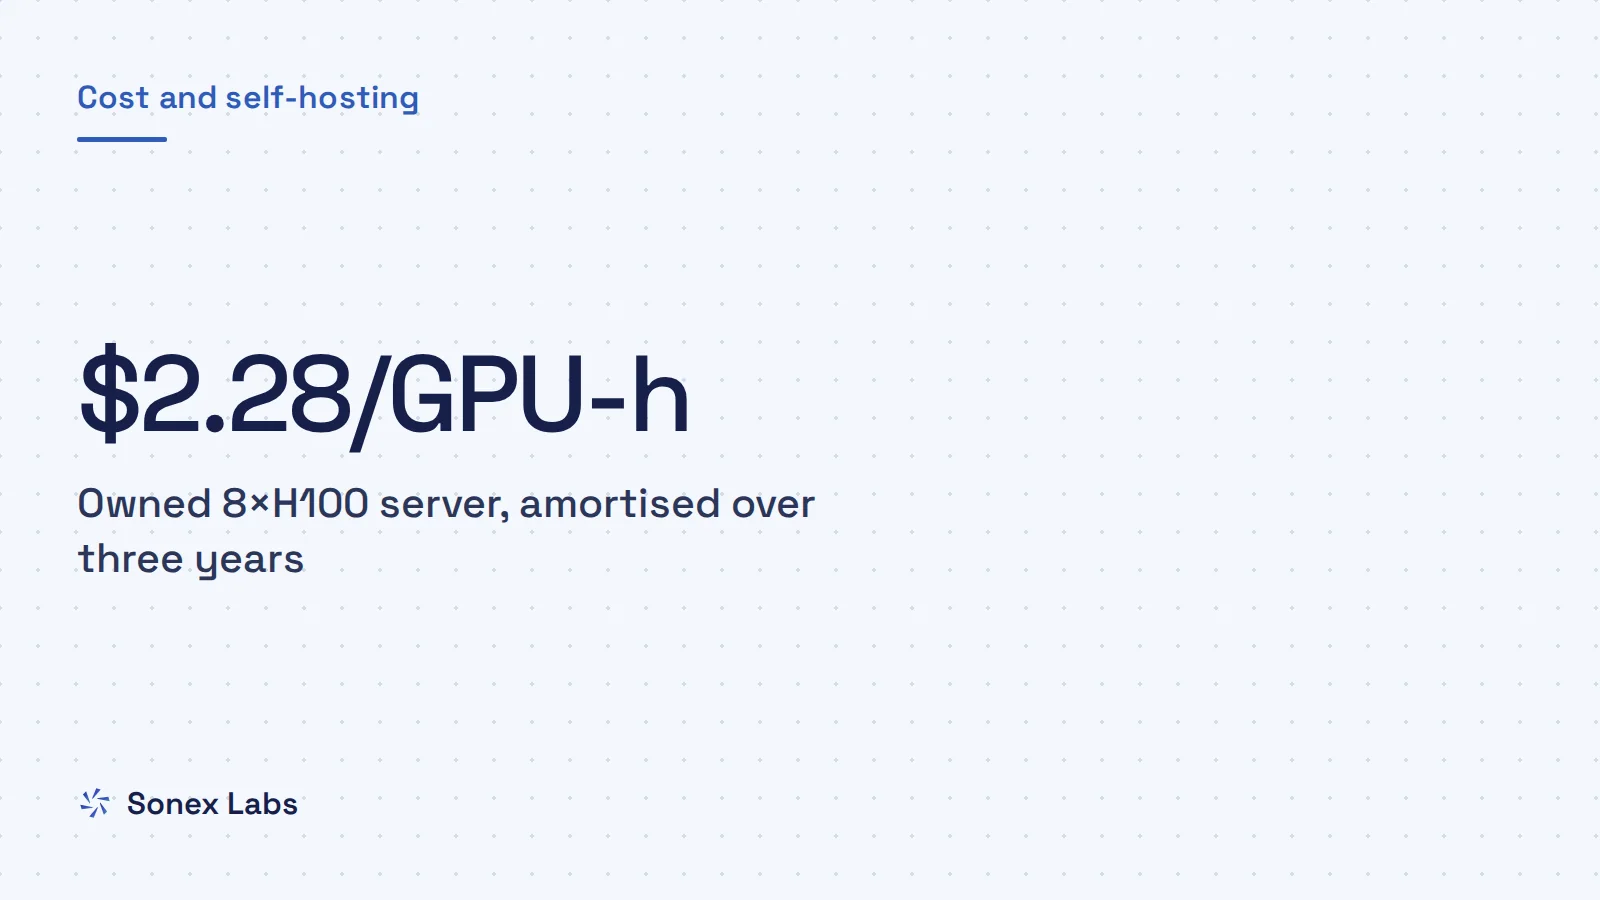
The amortised cost of an owned GPU is its depreciation plus power, space and maintenance, divided by the hours it can serve. A new 8×H100 HGX server costs about $250,000 to $320,000 according to third-party estimates; NVIDIA publishes no list price. The worked figure uses $285,000, 10 kW for the whole server (an assumption, not sourced), $300 per kW-month for colocation and 10% of the price a year for maintenance.
Without resale, that is $285,000 ÷ 36 = $7,917, plus 10 × $300 = $3,000, plus $285,000 × 10% ÷ 12 = $2,375, or $13,292 a month. Divided by 8 × 730 GPU-hours, it comes to $2.28. If the server still fetches today's used value of $195,000 after three years, which is optimistic, depreciation falls to $2,500 a month and the cost to $1.35. Compare AWS's three-year rate of $2.97, Azure's $3.84 and RunPod Community at $2.69.
Owning cuts hardware cost but does not fix low utilisation. A GPU busy 20% of the time costs five times its amortised rate per useful hour, whether you own it or rent it. You also take on resale risk, procurement lead time, remote hands and your own spare. GMI Cloud, a GPU-cloud vendor and so not neutral, puts the break-even at 60 to 70% sustained utilisation, which voice traffic rarely reaches. Buy only for a base load you can prove around the clock.
Spot capacity and consumer cards
Spot capacity is the cheapest line in most tables, such as Azure's H100 at $1.29 or E2E's at ₹70. Because the provider can reclaim it at short notice, a live call on it can drop unless your system moves the session mid-call. Use it for batch transcription, evaluations and fine-tuning, not for live calls.
Consumer cards such as the RTX 4090 and 5090 are the cheapest cells on RunPod, at $0.34 to $1.19 an hour. NVIDIA's GeForce driver licence has historically restricted data-centre use, so check the current terms before building a commercial service on them.
What India's prices buy, and what is missing
Hosting in India buys data residency and shorter network paths, not cheaper hardware. With GST, E2E's L4 costs $0.61 an hour against RunPod Secure's $0.59, and its L40S $1.27 against $1.09. An H100 costs $4.10 with GST at JarvisLabs' Indian region and $4.32 to $4.71 at E2E, more than Lambda's $3.29 or RunPod's $2.69 to $3.99. If your customers or regulator require data to stay in India, budget for that; if not, location is a latency choice.
Some prices are missing because they are not published. Vast.ai's marketplace prices change hourly and did not render, so quote a dated screenshot if you use them. RunPod, Lambda and Modal negotiate reservations privately, and E2E quotes monthly and annual plans per deal. Ask Indian providers for the term, notice period and exit terms of any committed rate in writing before you budget on it.
amortised $ per GPU-hour =
  [ (price - resale) / 36  +  kW x colo $ per kW-month  +  price x maintenance% / 12 ]
  / (GPUs x 730 x availability)

8x H100, no resale:   (7,917 + 3,000 + 2,375) / (8 x 730)   = $2.28
8x H100, $195k resale: (2,500 + 3,000 + 2,375) / (8 x 730)  = $1.35
1x L40S server:        (278 + 180 + 83) / (1 x 730)          = $0.74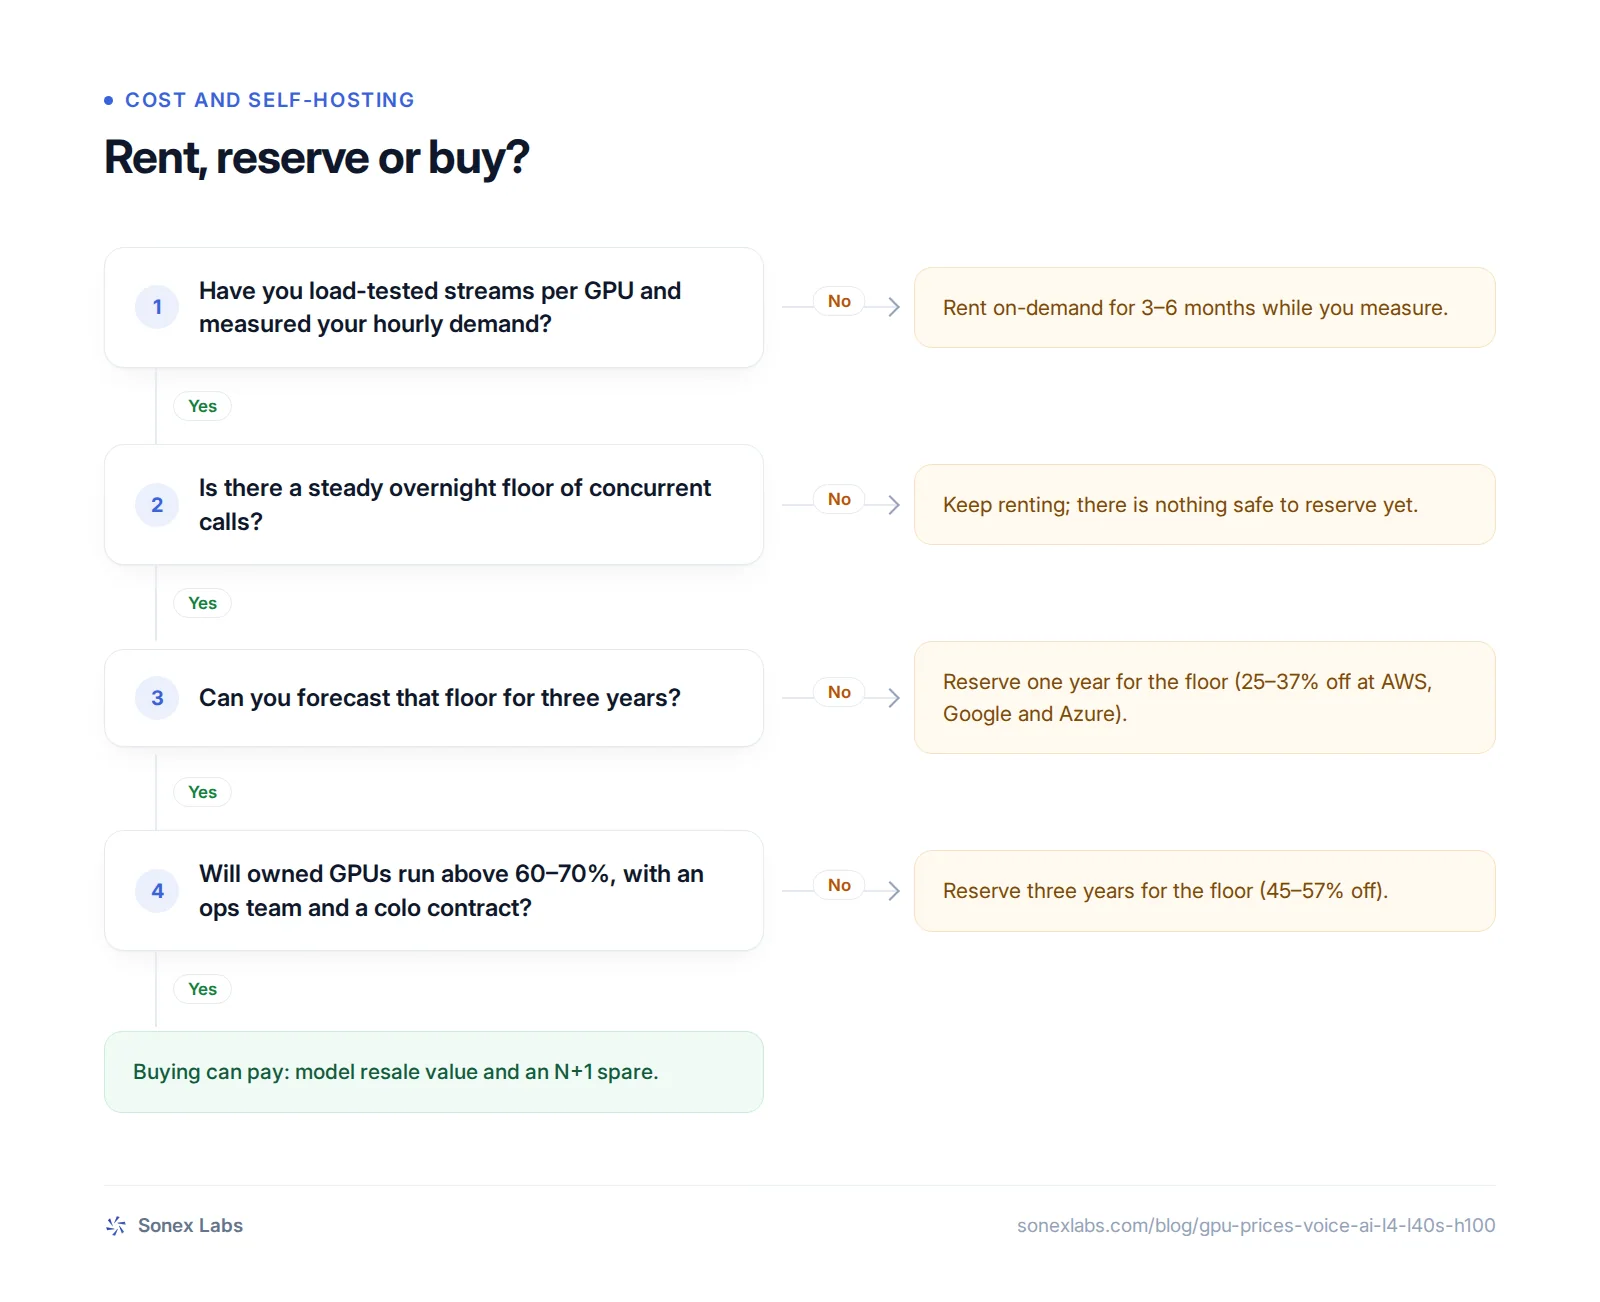
Sources
- Vantage: AWS g6.xlarge (1× L4) prices (checked 24 Oct 2026)Secondary
- Vantage: AWS g6e.xlarge (1× L40S) prices (checked 24 Oct 2026)Secondary
- Vantage: AWS p6-b200.48xlarge (8× B200) pricesSecondary
- Holori: AWS p5.48xlarge (8× H100) prices, us-east-1 (updated 23 Oct 2026, checked 24 Oct 2026)Secondary
- gcloud-compute.com: g2-standard-4 (1× L4), us-central1 (updated 18 Oct 2026)Secondary
- gcloud-compute.com: a3-highgpu-1g (1× H100), us-central1 (updated 18 Oct 2026)Secondary
- Azure Retail Prices API (NC40ads H100 v5, East US, queried 24 Oct 2026)Official
- Lambda: GPU cloud pricing (checked 24 Oct 2026)Official
- RunPod: pricing (checked 24 Oct 2026)Official
- Modal: pricing (checked 24 Oct 2026)Official
- CoreWeave: pricing (checked 24 Oct 2026)Official
- Together AI: pricingOfficial
- Fireworks AI: pricingOfficial
- E2E Networks: pricing, excludes 18% GST (checked 24 Oct 2026)Official
- E2E Networks: NVIDIA H100 page, on-demand and committed rates (checked 24 Oct 2026)Official
- JarvisLabs: H100 price in India, India-region rate (updated 20 Oct 2026)Official
- Yotta Shakti Cloud: pricing (checked 24 Oct 2026)Official
- Vast.ai: pricingOfficial
- IntuitionLabs: data-centre GPU prices, 5 September 2026Secondary
- American Compute: GPU server values, October 2026Secondary
- GPUDojo: L40S price tracker, 21 October 2026Secondary
- Data Center Knowledge: colocation pricing in 2026Secondary
- GMI Cloud: H100 rent vs buy analysisSecondary
- NVIDIA: L4 Tensor Core GPUOfficial
- NVIDIA Riva: ASR performance tablesOfficial
- NVIDIA TTS NIM: performanceOfficial
- NVIDIA NIM: LLM benchmarksOfficial
- Softcery: the self-hosted voice AI stack, 3 July 2026Secondary
- Daily: announcing Pipecat PhoneLLM alpha 1, 27 August 2026Official
- open.er-api.com: USD exchange rates, 24 October 2026Official
Change log: 24 Oct 2026, First published; prices checked 24 October 2026. Later the same day, rewritten as one continuous article: added what each kind of seller and term means, which card does which job, JarvisLabs' Indian-region H100 (₹330.48 plus GST), E2E's committed H100 rate as a starting price, and Yotta's GST treatment as not stated; the India range in the summary is now ₹330 to ₹379. Refreshed quarterly